V Talks Tech · 11 NOV 2026
Data Structures #6: The Tree - Branching Out
Trees transition data from linear to hierarchical. Using nodes with multiple pointers, Binary Search Trees offer O(log n) performance, driving databases, DOMs, and file systems.
- By
- Vibhishan Ranga
- Read
- 6 min
- Tags
Up until now, every data structure we have explored has been linear. Arrays, Linked Lists, Stacks, and Queues all represent data in a straight line, meaning one item comes directly after another. But the real world is rarely that simple. Data is often hierarchical.
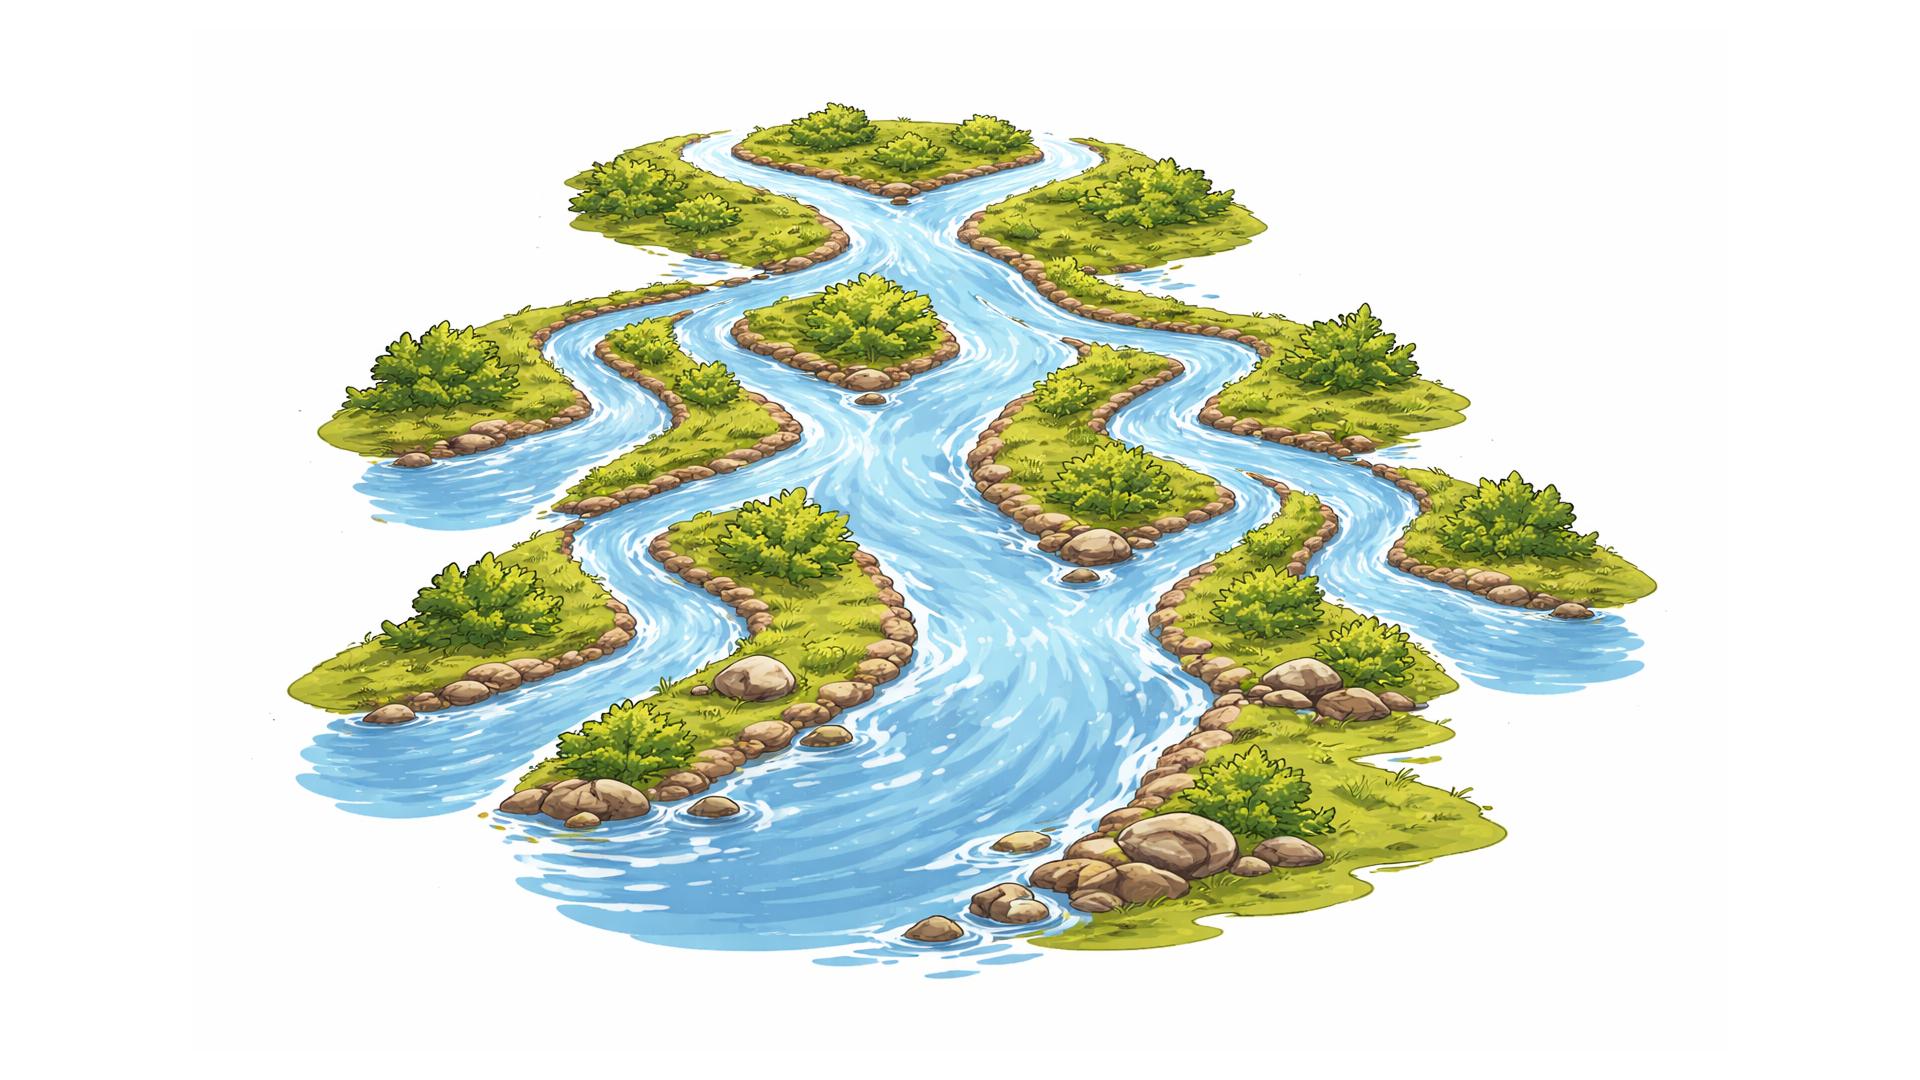
Take a look at the cover image above. Imagine a massive river flowing through a landscape. This main river does not just stay in a single channel. It splits into smaller tributaries, which then branch out into even smaller streams until they finally trickle out into the soil.
In computer science, this is exactly how a Tree works, although we usually draw them upside down. The main river is the Root. The points where the water splits are the Internal Nodes, and the tiny streams where the water ends are the Leaves. Trees allow us to model complex, branching relationships that linear data structures simply cannot handle efficiently.
Under the Hood: Nodes with Multiple Paths
A Tree is built on the exact same foundation as a Linked List: the Node. However, instead of a node having a single next pointer that leads to one destination, a tree node can have multiple pointers that link to its Children.
While a node could technically have any number of children, similar to folders on your computer, the most fundamental and widely used variation is the Binary Tree. In a Binary Tree, each node is restricted to a maximum of two children, which are traditionally called left and right.
      [Root]
      /    \
  [Left]  [Right]
   /  \      \
[L1] [L2]    [R1]
The Game Changer: The Binary Search Tree (BST)
A standard Binary Tree is just a structural shape. The true power of a tree is unlocked when we apply a specific sorting rule to it, creating what is known as a Binary Search Tree (BST).
The BST rule is simple but profound:
- Everything to the left of a node must be smaller than the node.
- Everything to the right of a node must be greater than the node.
Because of this specific arrangement, every time you make a decision to go left or right while searching, you eliminate half of the remaining tree. This is the exact same logic as a Binary Search algorithm in an array, but here it is built directly into the memory structure itself. Instead of calculating mathematical midpoints, you simply follow the structural pointers.
Performance Profile: The Logarithmic Sweet Spot
When a Binary Search Tree is balanced, meaning the left and right sides are roughly equal in depth, its performance is incredibly efficient.
- Search / Access:
O(log n) - Insertion:
O(log n) - Deletion:
O(log n)
However, there is a significant catch. If you insert sorted data into a standard BST like inserting the numbers 1, 2, 3, 4, 5 in that exact order, the tree will just keep adding nodes to the right child. The tree becomes entirely unbalanced and essentially degrades into a standard Linked List. In this worst-case scenario, all operations drop to a disastrous O(n) time complexity. Advanced tree structures like AVL Trees or Red-Black Trees are specifically designed to auto-balance themselves to prevent this degradation.
Language Implementations: Building the Branches
Unlike arrays or hash maps, most programming languages do not provide a primitive, out-of-the-box generic "Tree" data structure that you just instantiate. Because trees are used to solve highly specific algorithmic problems, engineers usually build them manually from scratch, or they use them indirectly via specialized standard library maps.
C++: The Manual Node
In C++, you build the tree node manually using pointers, managing the memory allocations dynamically on the heap. This gives you absolute control over performance but requires careful memory management.
#include <iostream>

struct TreeNode {
    int val;
    TreeNode* left;
    TreeNode* right;

    // Constructor
    TreeNode(int x) : val(x), left(nullptr), right(nullptr) {}
};

int main() {
    TreeNode* root = new TreeNode(10);
    root->left = new TreeNode(5);
    root->right = new TreeNode(15);

    std::cout << "Root: " << root->val << std::endl;

    // Remember to clean up memory in a real application!
    delete root->left;
    delete root->right;
    delete root;
    return 0;
}
Java: Object References and TreeMap
In Java, you create a custom class relying on object references and let the Garbage Collector handle the cleanup. However, Java does provide a built-in Tree optimized specifically for key-value storage known as the TreeMap.
import java.util.TreeMap;

// Manual Implementation
class TreeNode {
    int val;
    TreeNode left;
    TreeNode right;
    TreeNode(int x) { val = x; }
}

public class Main {
    public static void main(String[] args) {
        // 1. Manual Tree
        TreeNode root = new TreeNode(10);
        root.left = new TreeNode(5);

        // 2. Built-in TreeMap (Under the hood, this is a self-balancing Red-Black Tree)
        TreeMap<Integer, String> map = new TreeMap<>();
        map.put(10, "Root");
        map.put(5, "Left Child");

        // Keys are kept in sorted order automatically!
        System.out.println(map.firstKey()); // Outputs: 5
    }
}
Python: Classes and References
Python engineers define custom classes for trees, utilizing object references to link everything together.
class TreeNode:
    def __init__(self, val=0, left=None, right=None):
        self.val = val
        self.left = left
        self.right = right

# Building the tree
root = TreeNode(10)
root.left = TreeNode(5)
root.right = TreeNode(15)

print(f"Root is {root.val}, Left child is {root.left.val}")
JavaScript: Prototypal or Class Nodes
JavaScript handles trees very similarly to Python, using custom classes to establish the node relationships.
class TreeNode {
    constructor(val) {
        this.val = val;
        this.left = null;
        this.right = null;
    }
}

const root = new TreeNode(10);
root.left = new TreeNode(5);
root.right = new TreeNode(15);

console.log(root.val); // 10
Famous Algorithms & Tricks
Trees are an absolute favorite topic for technical interviewers because they perfectly demonstrate your grasp of recursive thinking and complex pointer manipulation.
- Tree Traversals (Depth-First Search): How do you effectively print or read a tree? You use Depth-First Search.
- In-Order (Left, Root, Right): On a Binary Search Tree, this specific pattern prints the nodes in perfect ascending, sorted order.
- Pre-Order (Root, Left, Right): This pattern is exceptionally useful for making a deep copy or clone of an existing tree.
- Post-Order (Left, Right, Root): This is the ideal strategy for safely deleting a tree from memory, as it ensures you delete the children before you delete the parent node.
- Level-Order Traversal (Breadth-First Search): Instead of diving deep down a single branch, you read the tree level by level. You start at the Root, then read all immediate children, then all grandchildren. This algorithm requires importing the Queue data structure we learned about in our previous post to keep track of the levels.
- Inverting a Binary Tree: This is a legendary technical problem that famously failed a highly skilled software engineer during a Google interview. It simply involves visiting every single node in the tree and swapping its left and right pointers.
Conclusion: The Architecture of Information
Just like a river system dictates the flow of water across a continent, Trees dictate the flow of hierarchical information in computing.
Whenever you open a folder on your computer to see sub-folders inside a File System tree, whenever your browser renders a webpage using the Document Object Model tree, or whenever a database executes a blazing-fast query using B-Trees, you are relying entirely on the logic of branching nodes. They are the ultimate structural tool for organizing complex, real-world relationships.